Continue reading “Stop exposing production data in lower environments”
Newsletter reviews
Some quarters are about product launches. This one was about conversations — with quality engineering leaders, financial services and healthcare teams, and partners across the ecosystem. They kept coming back to one idea: when testing moves at machine speed, test data can’t keep up with human speed. Here’s what we shared, built, and learned.
Up to 90% of enterprise data is unstructured — claims forms, IDs, clinical notes, loan files — and most of it sits locked behind privacy, security, and residency rules. Your AI and QE teams need it; they just can’t use it. The UDA Proof of Value Program is a low-risk way to change that:
Legacy TDM quietly drains budgets — licensing, infrastructure, services, and the daily drag of managing masked copies of production data. Forrester’s TEI math puts it near $934K a year for a single modeled deployment. Garth Rose (Co-Founder & CEO) and Doug Smith (Director of Solutions Engineering) show how to cut that by 50–75% and put the savings toward the data foundation your AI initiatives need.
How do you test and train AI on real documents, contracts, and statements without exposing a single piece of sensitive production data? Ulas Kumar (AI Practice Lead, GenRocket) and Dave Zwicker (CMO, GenRocket) explored it live on September 23.
At one major bank, production data covered roughly 50% of test cases. The other 50% is where the biggest risks hide. Garth Rose and Stephen Benjamin (CU Lead – Test Data & Test Environment Management, Capgemini FS QE&T) explain why design-driven synthetic data is becoming essential for financial services:
PARTNERSHIP NEWS
AI assurance is only as trustworthy as the data behind it. Our partnership with Qapitol brings deterministic synthetic data and AI assurance into one compliance-ready workflow, from data provisioning to deployment validation.
AI assurance is only as trustworthy as the data behind it. Our partnership with Qapitol brings deterministic synthetic data and AI assurance into one compliance-ready workflow, from data provisioning to deployment validation.
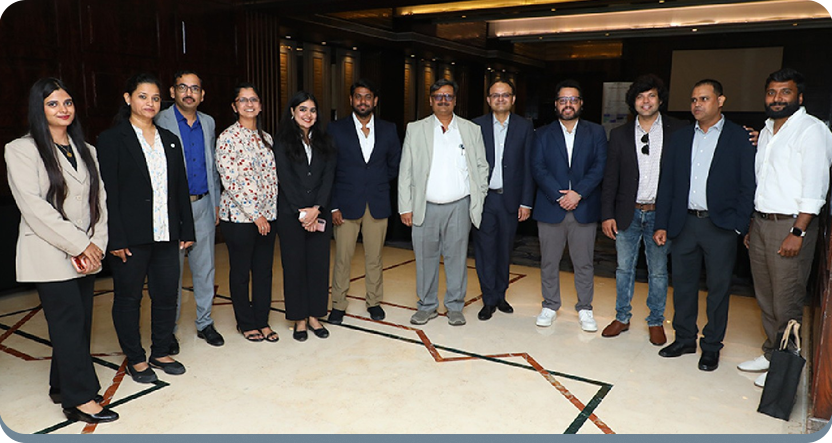
a fireside on what agentic QE demands, plus live DataConnect:tm: showcases. The ch’AI’ was hot; the questions were hotter.
live demos across core banking, insurance, and credit workflows.
two cities, buzzing booths, and new teams introduced to GenRocket. Congratulations, Infosys QE!
proud partner to 50,000+ engineers and QA leaders, August 19–21.
FRESH READS
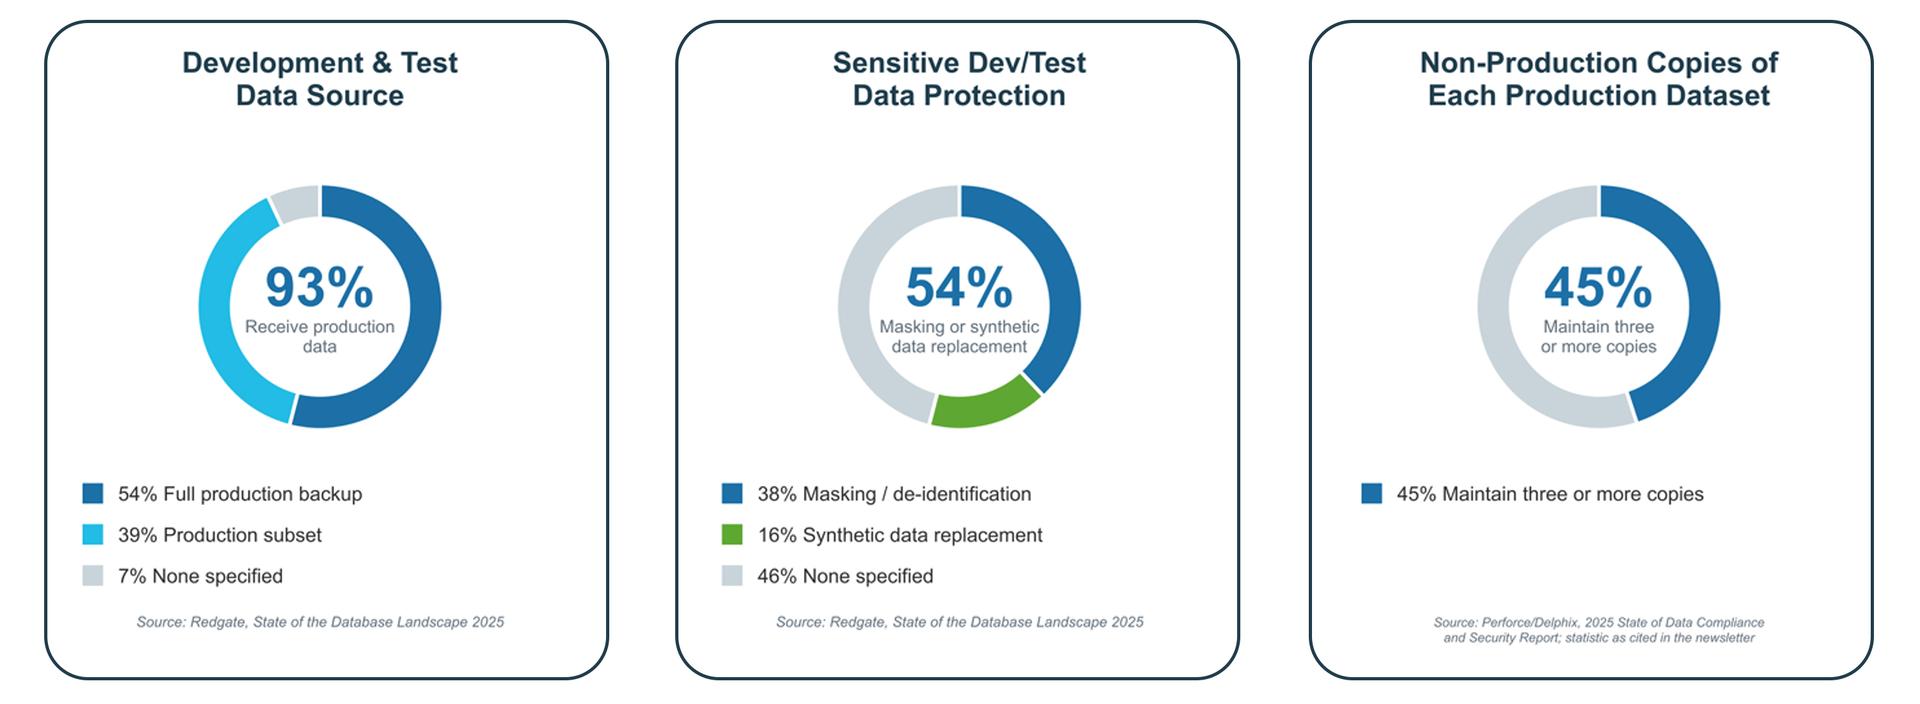
The Silent Multiplier — 93% of organizations hand dev and test teams production data, only 54% protect it, and 45% keep three or more copies. A practical roadmap to Protect, Expand, and Scale toward the Synthetic Enterprise:tm:.
Quarter after quarter, one thing keeps proving true: the future of testing won’t be built by improving yesterday’s approaches. It will be shaped by rethinking them, together. Thank you for being part of these conversations. We can’t wait to share what’s brewing for Q4.
If anything here maps to a project on your desk, reply and we’ll connect you with the right person.
Until next quarter,
— The GenRocket Team
93% of organizations provide development and test teams with production data — either full database backups or production subsets. Yet only 54% report protecting sensitive development and test data through masking, de-identification, or synthetic data replacement.
Enterprise development and AI teams increasingly need realistic unstructured data — documents, images and other content — for both software testing and AI training. But obtaining that data with the right conditions, complexity and realism, without exposing sensitive production information, presents an entirely new set of challenges.
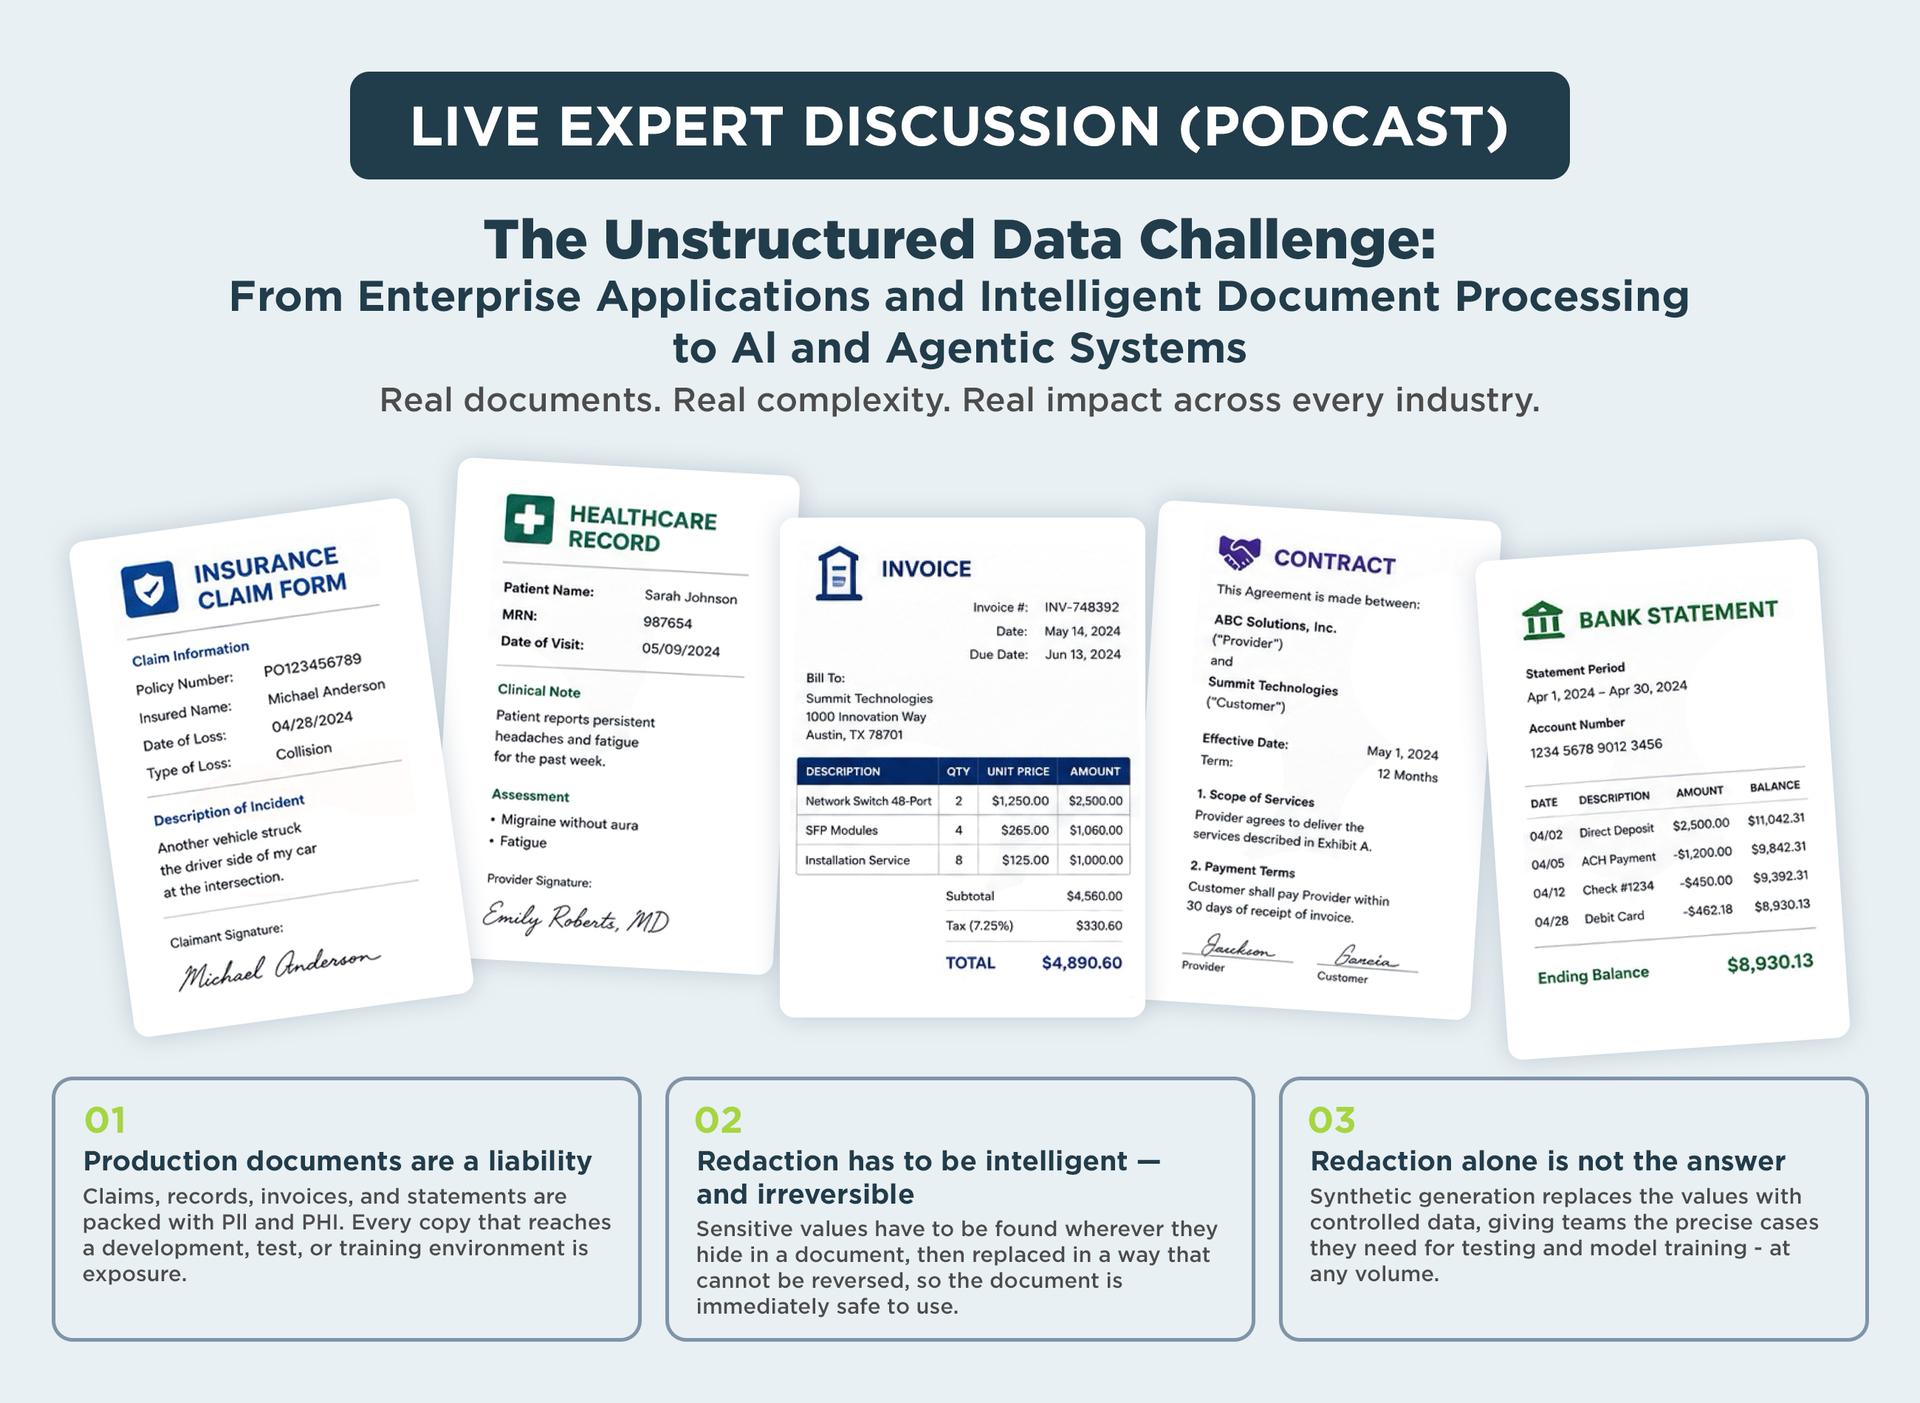
Enterprise development and AI teams increasingly need realistic unstructured data — documents, images and other content — for both software testing and AI training. But obtaining that data with the right conditions, complexity and realism, without exposing sensitive production information, presents an entirely new set of challenges.
GenRocket is expanding Enterprise Data Provisioning into one of the fastest-growing areas of enterprise data management: unstructured data for application testing and AI.
Enterprise Quality Engineering and AI initiatives increasingly depend on documents, images, text, and other forms of unstructured data. But much of the most valuable real-world data contains sensitive PII or PHI that cannot safely move into testing, development, or AI environments. And even when production data can be made available, it rarely provides the volume, variety, negative scenarios, and edge cases needed for comprehensive testing and AI model training and validation.
GenRocket customers and partners can now extend their existing Quality Evolution Platform deployment to address this challenge through the Unstructured Data Accelerator (UDA) Proof of Value Program.
Evaluate UDA Redact or UDA Generate independently-or combine them for end-to-end unstructured data provisioning.
AI-assisted detection, validation, and redaction of sensitive PIl/PHI in production documents for testing and AI.
$5,000 • 100 pages • 1-year license
No existing GenRocket platform deployment required
Ideal for: Organizations that need production-derived documents for testing or AI.
Path forward: Safely redact sensitive data, then expand to synthetic generation.
UDA-Generate
AI-assisted replacement of sensitive document values with engineered synthetic data for Quality Engineering and AI.
$5,000 • 5 templates • 1-year license
Leverage an existing GenRocket Platform deployment
Ideal for: GenRocket customers and partners extending synthetic data to unstructured data.
Path forward: Generate controlled synthetic documents with the volume, variety, and conditions you need.
UDA provides two complementary approaches to compliant unstructured data provisioning.
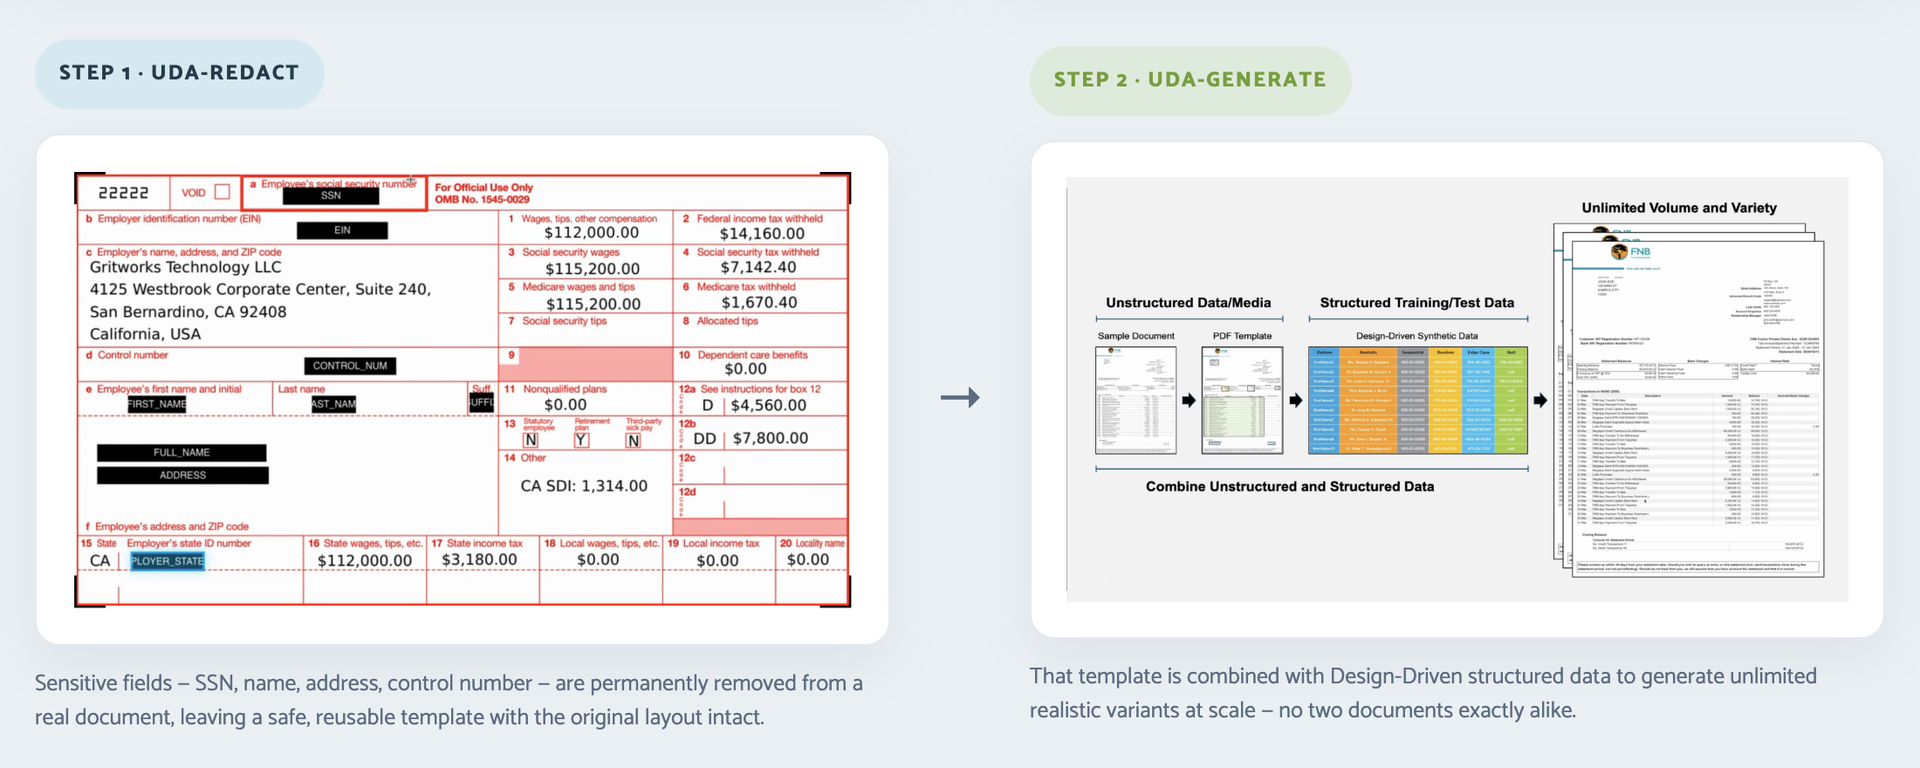
UDA Redact starts with existing production documents. AI-assisted detection identifies sensitive information, human validation confirms the results, and automated redaction removes PII/PHI while preserving the original document structure and real-world fidelity.
UDA Generate goes beyond what production can provide. It combines reusable document templates with GenRocket Design-Driven synthetic data to replace sensitive values and generate realistic variations with precisely controlled conditions, including positive and negative scenarios, rare edge cases, and data volumes on demand.
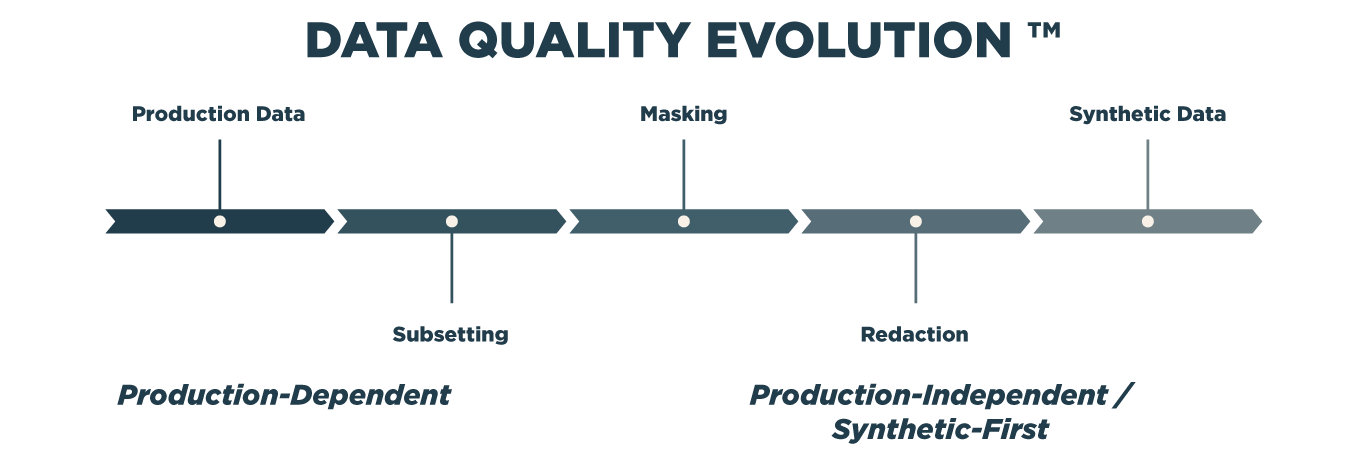
Together, these capabilities create an evolutionary path from production dependency to controlled synthetic data provisioning: start with real production documents, make them safe through redaction, transform them into reusable templates, and generate scalable synthetic data for Quality Engineering and AI initiatives. The combined workflow delivers the fidelity of production-derived data with the privacy, control, variety, and scale of synthetic data.
The POV program is designed to be flexible. Customers and partners can evaluate UDA Redact independently, evaluate UDA Generate using their existing GenRocket deployment, or combine both to demonstrate the complete unstructured data provisioning lifecycle.
See how far your existing GenRocket investment can take you.
Q2 brought meaningful momentum across GenRocket. We strengthened our platform to help enterprises perform the essential functions they rely on today-including data masking, subsetting, and secure test data provisioning-at lower cost, all within a single unified platform.
At the same time, new capabilities across synthetic data, AI-driven testing, and data privacy give teams a practical way to modernize at their own pace while preparing for future data requirements.
Here’s a quick look at what we’ve been building this quarter.
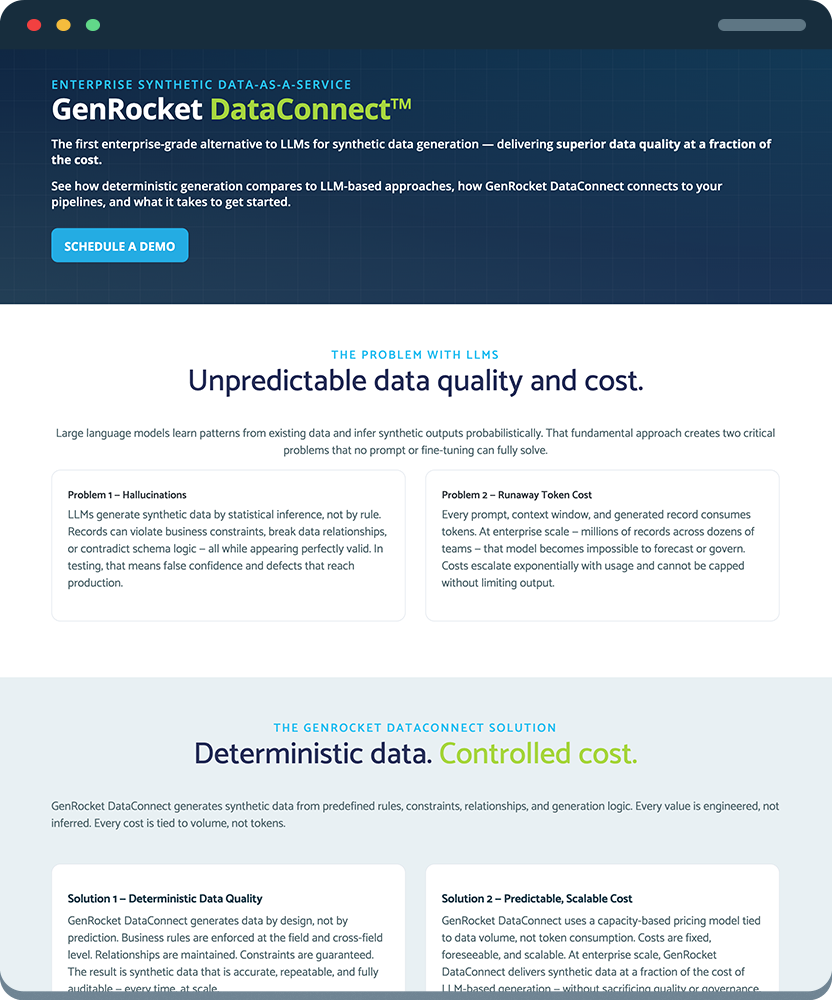
AI agents need reliable, testing-quality data-not unpredictable outputs.
GenRocket DataConnect™ delivers deterministic synthetic data on demand through REST APIs and MCP, helping teams test AI applications faster, securely, and without using production data.
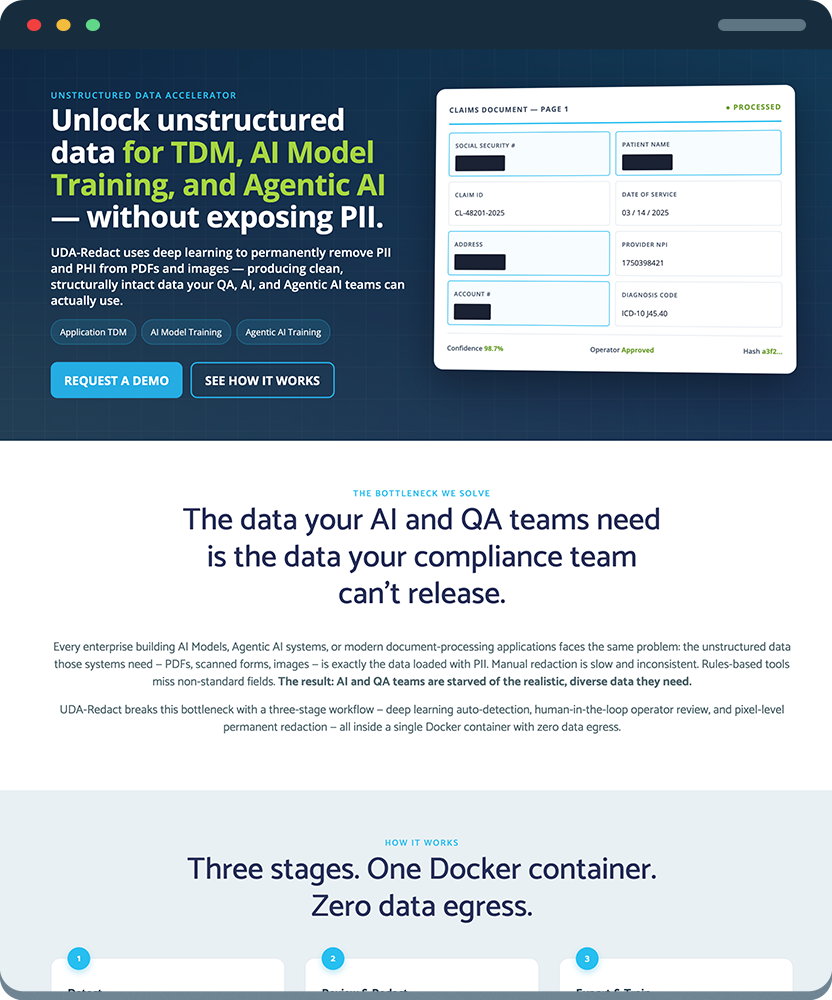
Sensitive data lives beyond databases-it also appears in documents, files, and free text.
UDA-Redact automatically identifies and redacts sensitive information in unstructured data, helping teams protect privacy while preserving realistic content for testing.
Garth Rose (Co-Founder & CEO) and Doug Smith (Director of Solutions Engineering) show how GenRocket brings the capabilities enterprises rely on today-including masking, subsetting, and secure data provisioning-together with synthetic data generation on one platform. See how organizations can reduce legacy TDM costs, modernize at their own pace, and prepare for an AI-ready future. Live demonstrations included.
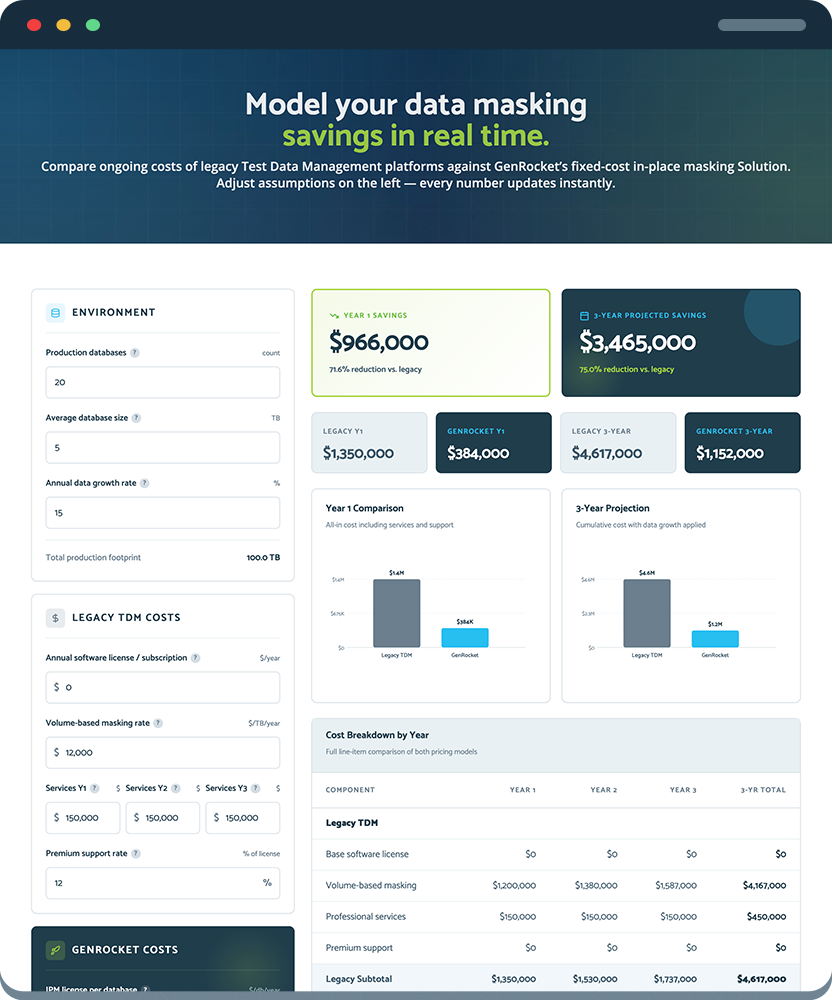
Use the TDM Cost Calculator to estimate the current cost of your legacy TDM infrastructure and project the potential savings from moving to GenRocket’s Quality Evolution Platform-a single platform supporting both production-data and synthetic-data requirements.
A candid discussion on the future of Test Data Management, the rise of synthetic data, and what AI means for the next generation of quality engineering. No slides, no pitch — worth your next commute.
From Test Data Management to Test Data Strategy: why leading QE organizations are moving beyond managing test data to strategizing it – combining quality engineering expertise with Design-Driven Synthetic Data.
Why Design-Driven Synthetic Data is the better fit for healthcare AI: enabling AI-ready healthcare testing with privacy-safe synthetic data — no PHI exposure, full test coverage, and a modern TDM foundation.
Enterprise data has outgrown the test data strategies built for it — here’s where the gap is widening, and what it takes to close it.
A practical framework for evaluating test data quality across ten dimensions — from coverage and compliance to speed of provisioning.
Masking production data is no longer enough — how synthetic data takes production data out of the risk equation entirely.
A real-world look at how a global enterprise replaced slow, manual test data provisioning across its HCM and API ecosystems.
What makes synthetic data trustworthy: referential integrity, business-rule validity, and data engineered to behave like the real thing.
A side-by-side cost breakdown of legacy TDM versus the Quality Evolution Platform — and exactly where the 50–75% savings come from.
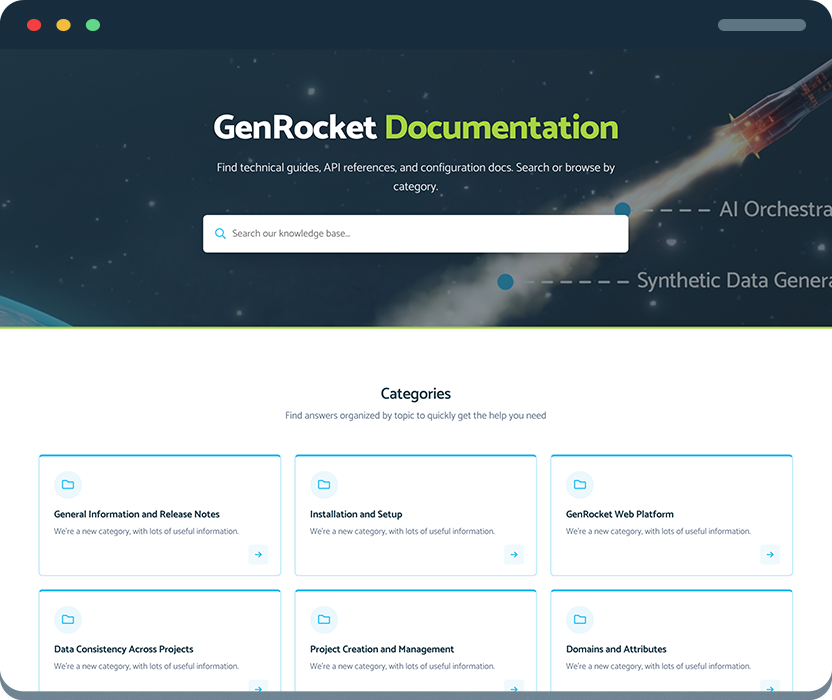
Answers, on demand. Our new Knowledge Base puts product documentation, how-to guides, and best practices in one searchable place — so your team can find what they need without waiting on a ticket.
The future of testing won’t be built by improving yesterday’s approaches — it will be shaped by rethinking them. We hope these resources spark fresh perspectives, practical ideas, and meaningful conversations.
If you’d like campaign assets, co-branded versions, or a joint session for one of your accounts, reply to this email — we’ll set it up.
Here’s a question worth sitting with: if your security team restricted production data access tomorrow, would your QA and AI teams still be able to do their jobs?
We just published an article on how leading enterprises are answering that question – with a practical framework for provisioning data that’s fit for purpose while reducing the dependency on production data. It combines subsetting, masking, redaction, and synthetic data into one coherent strategy, so security gets the governance it needs and quality engineering keeps the realistic data it needs, without an all-or-nothing tradeoff.
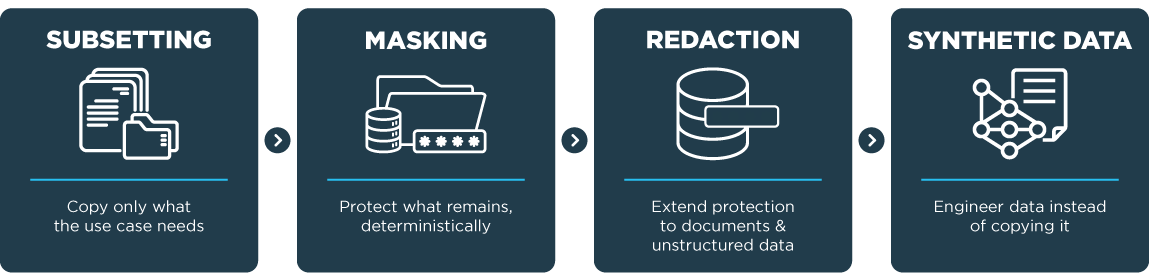
As privacy regulation, AI governance, and internal security policy increasingly limit how production data can be copied and used, quality engineering and AI teams need a clear, practical playbook for staying productive while reducing your dependance on sensitive production data. Our latest article offers exactly that.
It lays out an evolutionary strategy for provisioning data by combining the use of subsetting, to copy only what a use case actually needs; deterministic data masking, to protect what remains; intelligent redaction, to extend that same protection to unstructured documents; and synthetic data, to engineer test and training data instead of copying it at all.
We call this approach Enterprise Data Provisioning, and our Data Quality Evolution™ framework maps how organizations can adopt it incrementally, one application and one environment at a time, without disrupting the systems they already depend on or forcing a wholesale replacement project. The result: security teams get the data privacy, governance and auditability they need, and quality engineering and AI teams keep the realistic, fit-for-purpose data they need to do their work.
See how GenRocket can solve your toughest test data challenge with quality synthetic data by-design and on-demand